A small machine learning model learns weather forecasting and data blending straight from 18 kinds of instrument. Near the ground it beats the main US ensemble for up to 12 hours, but it trails operational systems higher up.
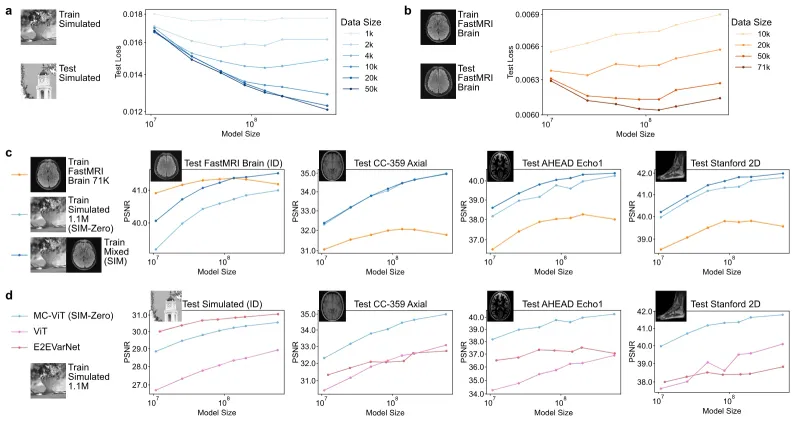
A preprint trains an MRI reconstruction model mostly on fake scanner data made from everyday photographs. On scans from other hospitals and machines, it beat methods trained on real patient scans.
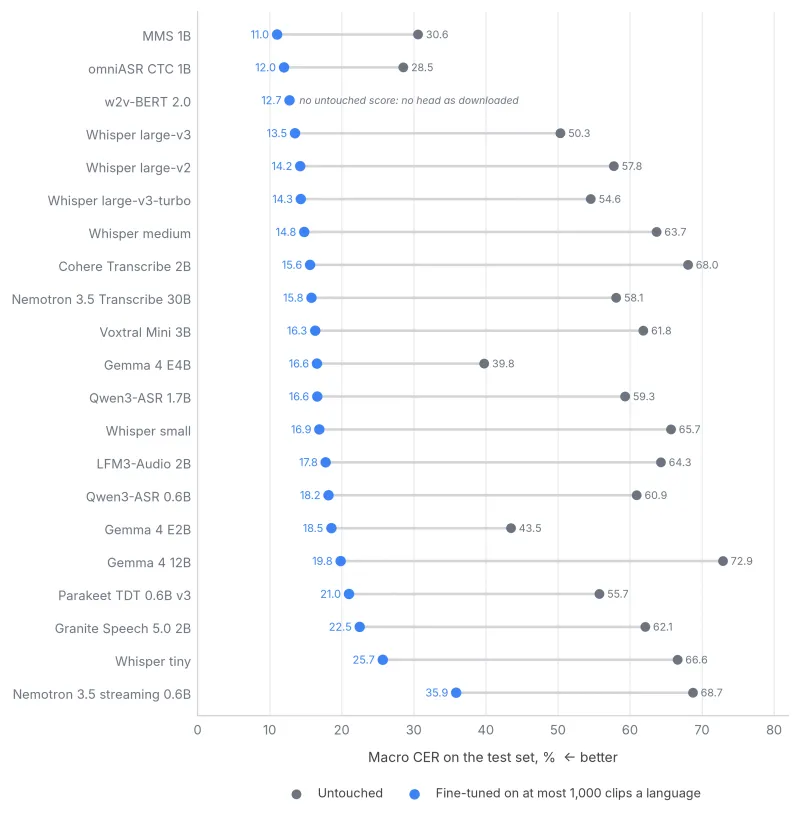
A large preprint fine-tunes 24 open speech recognisers on 50 low-resource languages. Every model improves sharply, but the output is still a draft that needs human correction.
A preprint benchmark of 12 image-counting tasks finds that free, off-the-shelf vision-language models are a strong starting point for estimating totals with a small human-labelled sample. Letting the model pick which images people check usually helps further.