How large language models are trained, aligned and improved: new research on reasoning, training data and architectures, rated for how close it is to use.
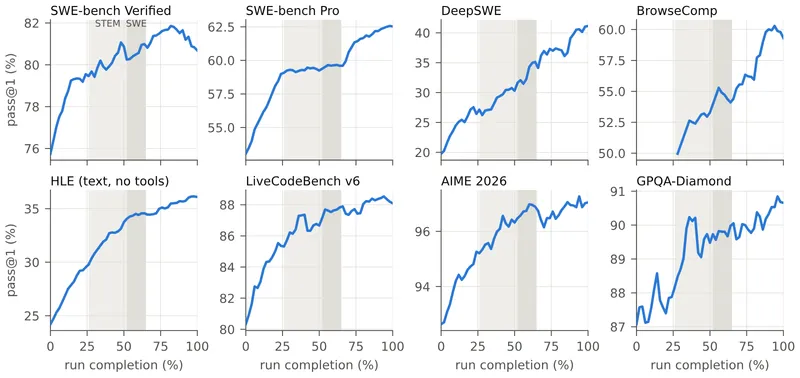
Reflection's first open-weight model, Beam, runs only a small part of itself for each word yet scores close to much larger open models on coding and agent tests. The evidence comes almost entirely from the company's own preprint.
A team at MBZUAI has published six language models for agent work, from phone-sized to server-sized, together with the data, code and checkpoints used to build them. The largest is competitive with open rivals on tool use, but trails closed models and has weak defences against hidden instructions.
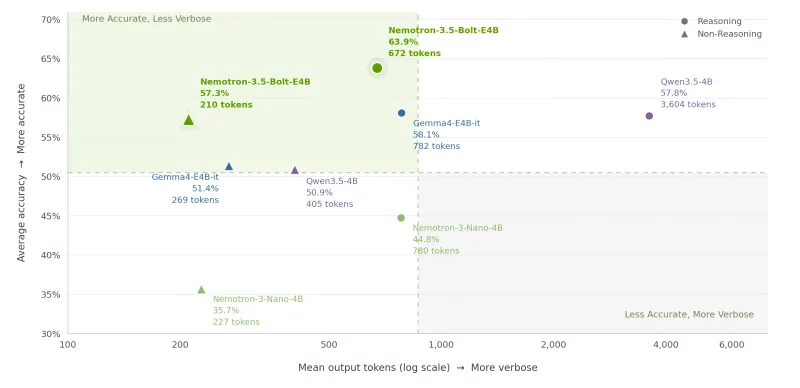
NVIDIA has retrained Google's small Gemma 4 model to follow instructions and use tools better, while keeping replies short. It fits in about 4 GB of memory and comes with a helper that speeds up replies.