A cheaper way to fine-tune small datasets without wiping out skills
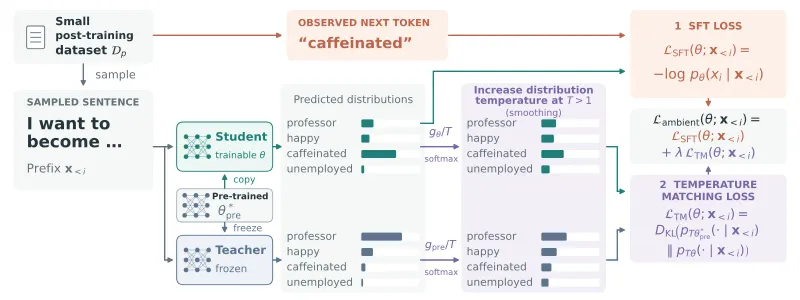
A new preprint adds one extra term to standard fine-tuning: the model must stay loosely close to its own earlier self. On small datasets this kept more knowledge and often scored higher, for about 10% more training compute.