An audit of five open medical image-reading models finds that a single accuracy score can hide total failure on one diagnosis. Two models never flagged a pneumothorax, yet explained their wrong answers fluently.
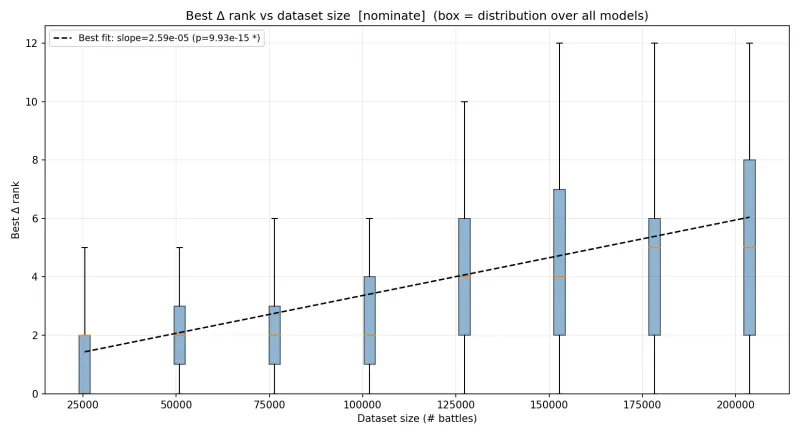
A preprint shows that votes, prompts and decoy models can lift a language model far up a crowd-voted ranking. The tests were simulations on public LMArena data, not attacks on the live site.
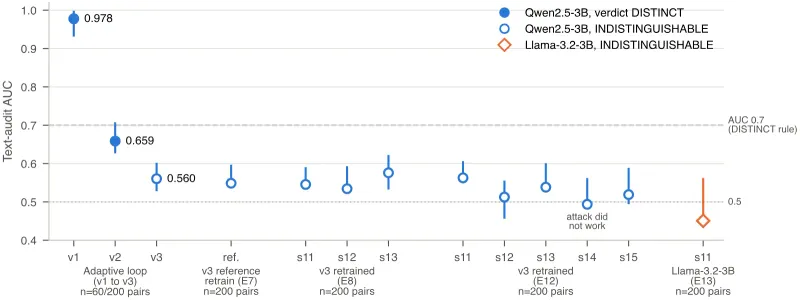
A preprint shows that a detector which nearly always catches a model that underperforms on purpose can be pushed to chance once the attacker adapts. Probes that read the model's internals mostly picked up fine-tuning in general, not the hidden behaviour.
A preprint finds that language-model forecasters usually follow a single planted news story once they read it. The multi-agent systems that search most widely are the ones most likely to find it.
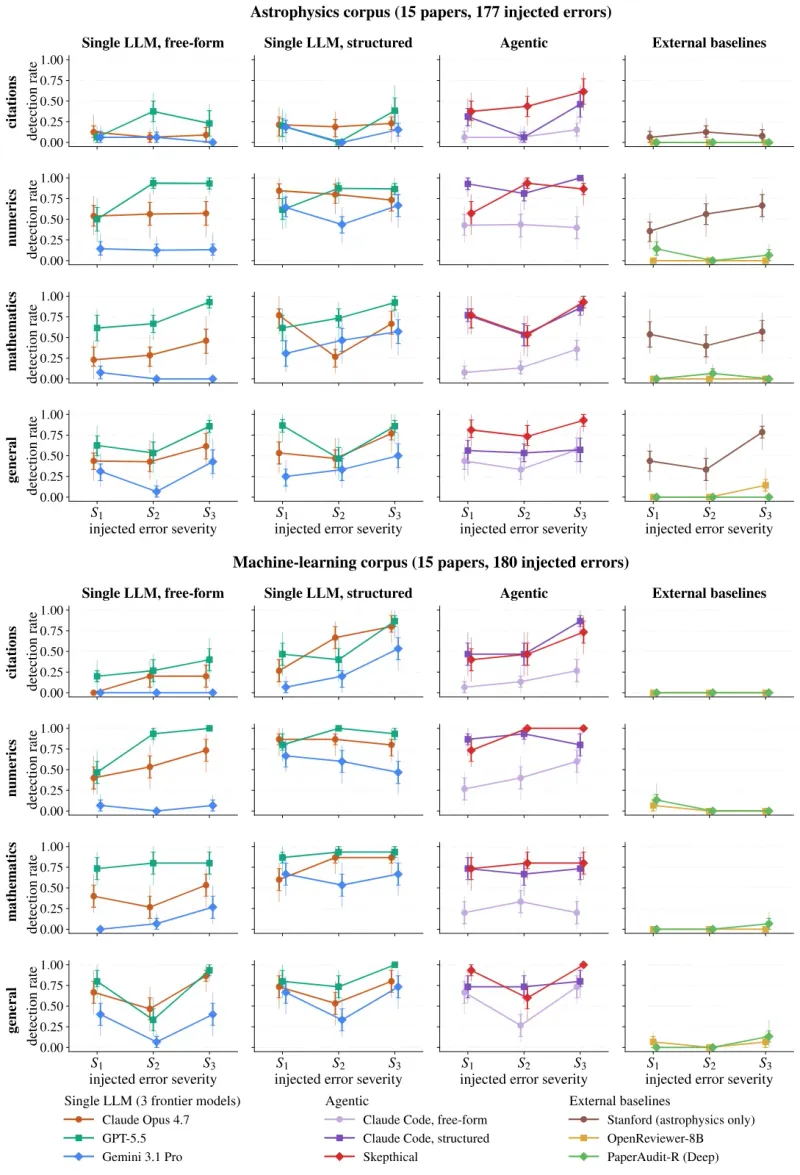
A new benchmark plants known mistakes in real scientific papers and counts how many AI reviewers catch. The model used makes the biggest difference; extra tools help only where the model has a gap.
A new open-source system produces a cryptographic proof that a server ran a specific model and gave a specific reply. Proving takes about 50 times as long as answering, and the exact integer model it proves is somewhat less accurate than the original.
A preprint finds that deepfake detectors built to read a heartbeat from facial skin colour mainly pick up frame-to-frame colour flicker. They also learn which collection a video came from. Common benchmark splits can hide this.
A new benchmark tells 21 image-reading AI models what a user considers private, then asks about a photo. Most answered anyway. Fine-tuning fixed much of this, but it cost some general ability.
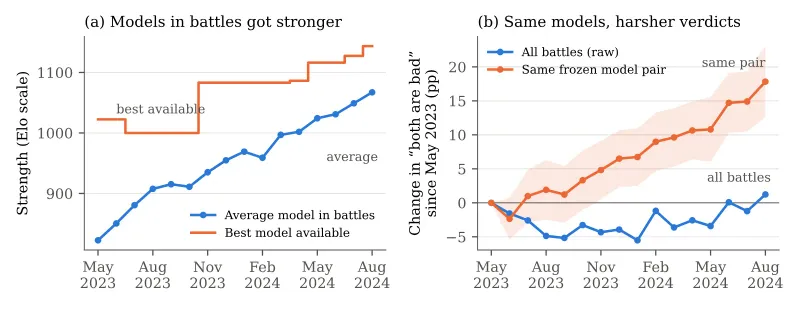
An analysis of 1.26 million blind votes on Chatbot Arena finds that verdicts on fixed AI models grew harsher while rankings held steady. The authors argue the bar moved, not the models. The paper is a preprint and has not been peer reviewed.